Under 50 ms is good latency for most everyday use, with 20 to 40 ms generally considered good, under 20 ms excellent, and anything above 100 ms likely to feel laggy. For websites, aim for a p75 time to first byte of 800 ms or less.
You may be seeing the problem right now: pages take too long to begin loading, an API request appears to hang, a video call breaks up, or a game feels delayed even though your speed test reports plenty of bandwidth. I troubleshoot this pattern regularly on bare metal servers, VPS platforms, and multi-tenant infrastructure. The ping number is useful, but it isn't the whole answer.
The right target depends on the workload. A general business website, a voice call, a game server, a database query, and an AI assistant each expose latency differently. The practical job is to measure the complete path, identify whether the delay comes from the network or the server, then fix the slowest phase without disturbing a healthy production system.
Table of Contents
- What Good Latency Feels Like and How to Fix It Fast
- Understanding Latency Jitter and Packet Loss
- Good Latency Targets by Use Case
- How to Test Latency Accurately
- Why Latency Is High and How to Diagnose It
- Proven Ways to Lower Latency for Good
- Choosing Your Target and Preventing Future Lag
What Good Latency Feels Like and How to Fix It Fast
The symptom usually sounds simple: "The site is slow," "The dashboard freezes," or "Users are complaining about lag." First, separate network round-trip time from application response time. A low ping to a nearby host doesn't prove that your website's DNS lookup, TLS negotiation, application code, database, and storage are responding quickly.
The immediate targets are straightforward. Keep ordinary internet and business traffic below 50 ms where practical, treat 20 to 40 ms as a solid result, and regard under 20 ms as excellent. Once latency exceeds 100 ms, users commonly notice lag in browsing, calls, and games. For a web origin, measure TTFB at p75, with 800 ms or less as the recommended good range, values from 800 ms to 1.8 seconds needing improvement, and anything above 1.8 seconds considered poor, as summarized in server response time guidance.
The fastest useful test from Linux is:
ping -c 10 example.com
curl -sS -o /dev/null -w 'dns=%{time_namelookup} connect=%{time_connect} tls=%{time_appconnect} ttfb=%{time_starttransfer} total=%{time_total}n'
On Windows PowerShell, use:
Test-Connection example.com -Count 10
curl.exe -sS -o NUL -w "dns=%{time_namelookup} connect=%{time_connect} tls=%{time_appconnect} ttfb=%{time_starttransfer} total=%{time_total}n"
If ping is low but TTFB is high, stop blaming the access circuit. Check the origin server, PHP or application workers, database queries, and storage. If both ping and TTFB rise at the same time, inspect routing, distance, congestion, packet loss, and jitter.
Production observation: On shared VPS infrastructure, the first useful distinction is often whether every tenant slows together or only one application does. A broad increase points toward the path or host node. One slow site usually points toward its process pool, database, or storage workload.
A Tampa small business may only need a responsive local or regional origin and clean caching. An enterprise serving users across several regions may need edge delivery, regional placement, and percentile monitoring. The rest of the diagnosis should follow the workload, not a universal ping score.
Understanding Latency Jitter and Packet Loss
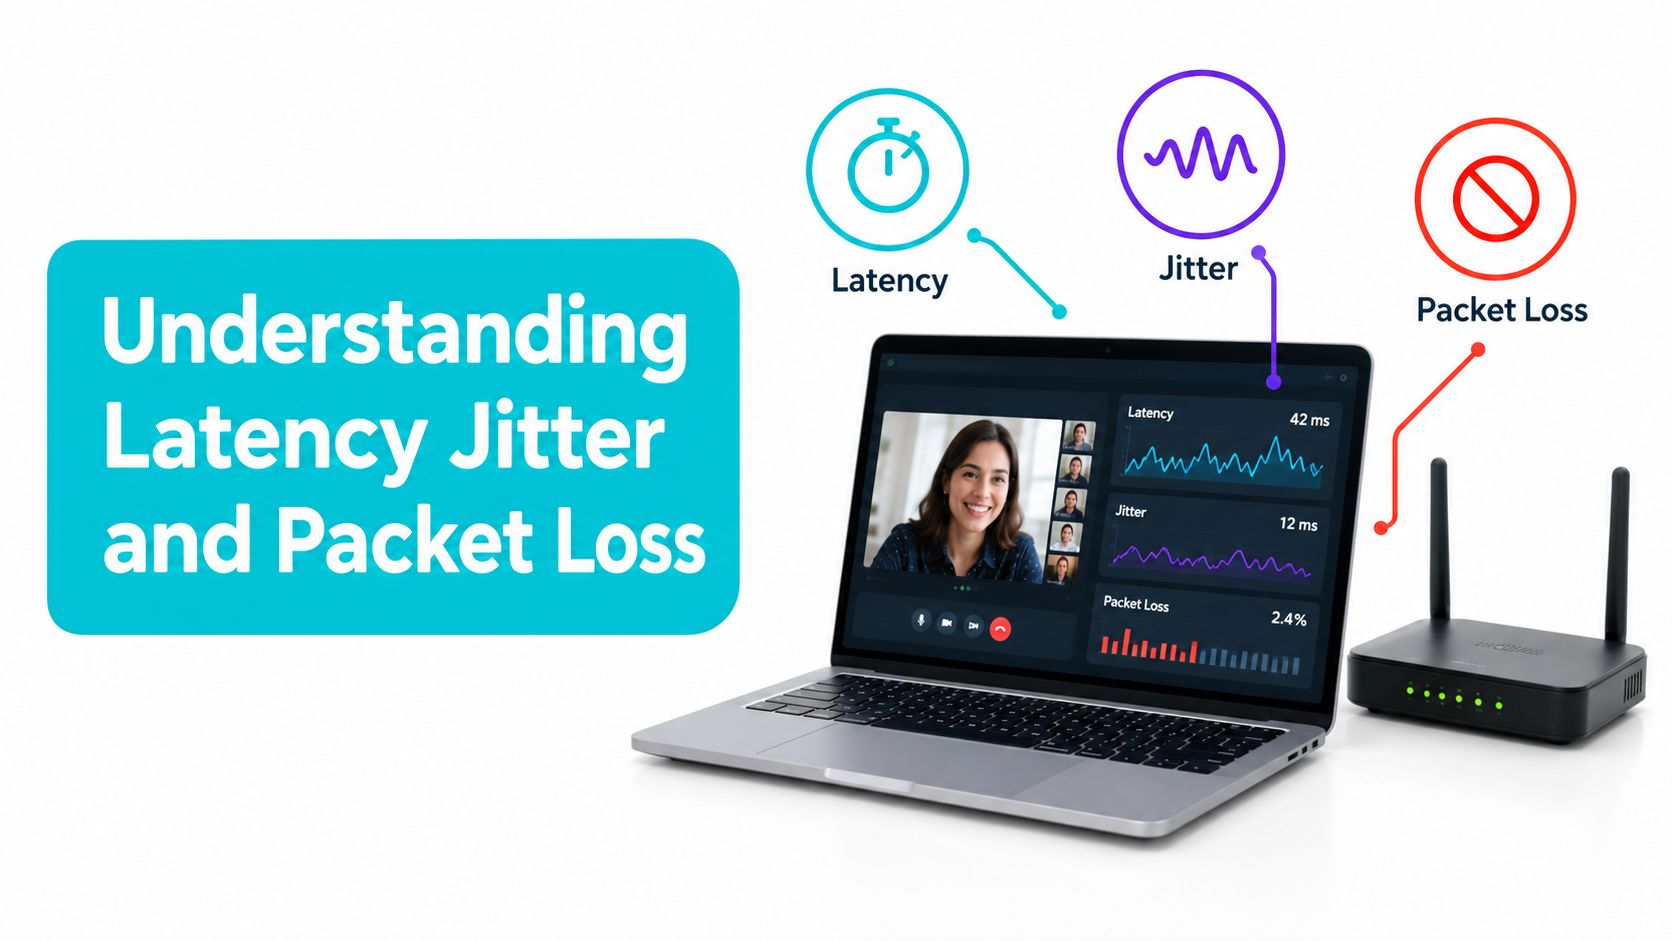
Latency is the delay a packet experiences while traveling between two points, commonly represented by round-trip time in milliseconds. Think of it as the time required for a technician to send a request to a server and receive the acknowledgment. Bandwidth describes how much traffic the connection can carry, but it doesn't tell you how quickly the first response arrives.
AWS defines the related terms clearly: latency is the time for a packet to travel from source to destination, jitter is the variation in latency between packets, and packet loss is traffic that isn't delivered. The definitions are available in the AWS hybrid connectivity performance documentation.
Why bandwidth doesn't guarantee responsiveness
A high-bandwidth connection can still feel slow. A large link may transfer a substantial volume of data once the transfer starts, while a delayed first packet, a congested queue, or repeated packets makes every interaction feel late. That's why a website can have excellent download capacity and poor checkout responsiveness at the same time.
Consider a request from a browser to an origin server:
Browser
  |
  | DNS lookup
  | TCP connection
  | TLS negotiation
  | HTTP request
  v
Origin server
  |
  | Application and database work
  v
First response byte
  |
  | Content transfer
  v
Browser
End-to-end response time includes more than ping. DNS lookup, TCP setup, TLS setup, server processing, and content transfer can each add delay. A fast network path can't compensate for an origin that waits on a saturated worker pool or a slow database query.
Jitter and loss affect real-time traffic
A stable 45 ms connection can feel better than one that alternates between short and long delays. Voice and video applications need packets to arrive at a regular pace. Jitter forces buffering or causes gaps, while packet loss can create missing audio, frozen video, retransmissions, or game-state corrections.
Run a simple baseline:
ping -c 20 example.com
Look at the minimum, average, maximum, and packet loss values. A wide spread between the minimum and maximum suggests inconsistency, but ping alone doesn't identify the hop responsible. For that, use MTR in the next testing stage and compare results at different times.
Low average latency with unstable maximum latency is not a healthy real-time path.
Good Latency Targets by Use Case
The question "what is a good latency speed" needs a workload attached to it. General browsing can feel acceptable below 100 ms, while video calls are commonly comfortable below 50 ms, cloud gaming is often targeted below 40 ms, and competitive gaming often needs below 30 ms, according to latency testing guidance.
For websites, don't use ping as the primary application metric. TTFB includes network travel and origin processing, so it shows whether the delay is between the user and server, inside the server, or both. Google Core Web Vitals also evaluates user visits at the 75th percentile. Its good thresholds include LCP at 2500 ms or less, INP at 200 ms or less, and CLS at 0.1 or less, as documented by Google's Core Web Vitals thresholds.
| Workload | Good Target | Acceptable Range | Needs Attention |
|---|---|---|---|
| General browsing | Below 100 ms | Below 150 ms for broad usability | Above 100 ms may be noticeable |
| Web origin and TTFB | p75 TTFB at or below 800 ms | 800 ms to 1.8 seconds | Above 1.8 seconds |
| Interactive web application | Below 200 ms | 200 ms to 500 ms | Above 500 ms, especially above 1 second |
| APIs and SaaS dashboards | Below 200 ms | 200 ms to 500 ms | Above 1 second |
| Voice and video calls | Below 50 ms | Up to 100 to 200 ms | Persistent delay, jitter, or loss |
| Cloud gaming | Below 40 ms | Higher values may remain playable | Rising jitter or loss |
| Competitive gaming | Below 30 ms | Depends on the game and route | Consistent delay above the target |
| AI chat and APIs | Low end-to-end latency, including TTFT | Depends on model and workflow | Slow first token or inconsistent tail latency |
For interactive web applications, a response under 200 ms is a practical target. A response from 200 to 500 ms may be acceptable for a distant, single-region origin, while 500 ms to 1 second is noticeable and more than 1 second needs attention, based on interactive response-time guidance.
Gaming requires more than a good average. Jitter and packet loss can make a connection feel poor even when its mean ping looks reasonable. If you're evaluating infrastructure for a game server, compare the actual player routes and server region in ARPHost's gaming VPS guidance, then validate with measurements from the players' networks.
AI introduces another layer. Users often judge an assistant by time to first token, or TTFT, followed by token streaming consistency. Recent 2026 benchmark material describes sub-second TTFT as an important product metric, with some mainstream systems under 600 ms and best-performing systems closer to 350 ms, while optimized stacks can exceed 200 tokens per second, as reported in LLM API latency benchmarks for 2026. Those figures apply to the cited benchmark context, not every model or deployment. For an AI service, measure the complete request path and its p95 or p99 tail, not only network ping.
How to Test Latency Accurately
Start with a Linux host running a current Debian or Ubuntu release, or Windows with PowerShell. Install MTR on Debian or Ubuntu before testing:
sudo apt-get update
sudo apt-get install -y mtr-tiny traceroute curl
On Rocky Linux or another Red Hat family system:
sudo dnf install -y mtr traceroute curl
Step 1 Measure round-trip time
Run enough probes to see variation rather than trusting one result:
ping -c 20 example.com
A healthy result has no packet loss and a narrow relationship between minimum, average, and maximum values. The exact number depends on distance and workload. Don't treat an isolated high result as proof of a persistent fault.
Windows equivalent:
Test-Connection example.com -Count 20
Step 2 Find path changes and loss
Use traceroute to see the route:
traceroute -n example.com
Linux may use UDP probes by default. If a firewall filters those probes, try ICMP:
traceroute -I -n example.com
MTR combines repeated probes with hop statistics:
sudo mtr -rwzc 50 example.com
A realistic report includes columns such as Last, Avg, Best, Wrst, and StDev. Intermediate hops may deprioritize or suppress diagnostic replies, so a single star or high intermediate value isn't enough. Concern rises when loss or increased latency continues through later hops and reaches the destination.
Step 3 Measure the web request phases
Use curl's timing fields:
curl -sS -o /dev/null
  -w 'dns=%{time_namelookup}nconnect=%{time_connect}ntls=%{time_appconnect}nttfb=%{time_starttransfer}ntotal=%{time_total}n'
Interpret the largest interval. A long DNS value suggests resolver or delegation issues. A large gap before TLS suggests connection or path delay. A long gap before TTFB usually points toward the origin or upstream application. A long total time after TTFB often means a large response or slow transfer.
For repeated samples:
for i in $(seq 1 10); do
  date -Is
  curl -sS -o /dev/null -w 'ttfb=%{time_starttransfer} total=%{time_total}n'
done
Step 4 Verify from more than one location
Run tests from the affected user's network, the hosting server, and an independent external probe. A result is actionable when the pattern repeats across samples and locations. For a deeper procedure, use ARPHost's network latency testing guide.
Why Latency Is High and How to Diagnose It
I rank causes by what appears most often in multi-tenant environments. Distance and routing come first, followed by congestion and loss. After that, DNS and connection setup, overloaded application workers, and storage or database contention account for many "the network is slow" reports.
Start with the path
Run MTR from the application host toward the user-facing destination:
sudo mtr -rwzc 100 example.com
If the destination shows stable loss and latency, but one intermediate hop reports a problem that disappears later, that hop may rate-limit diagnostic traffic. If the high values continue to the destination, investigate the route, provider congestion, or an overloaded edge device.
Compare a normal period with the incident window:
ping -c 20 example.com
sudo mtr -rwzc 50 example.com
Distance can't be optimized away. A server placed far from a user base adds unavoidable round trips, while an inefficient route can add avoidable hops.
Separate connection delay from server delay
Use curl with phase timings:
curl -sS -o /dev/null
  -w 'remote=%{remote_ip}nhttp=%{http_code}ndns=%{time_namelookup}nconnect=%{time_connect}ntls=%{time_appconnect}nttfb=%{time_starttransfer}ntotal=%{time_total}n'
A short connection phase followed by a long TTFB points to origin processing. Check the web server and application logs at the same timestamp:
sudo journalctl --since "15 minutes ago" -u nginx
sudo journalctl --since "15 minutes ago" -u php8.2-fpm
The service name varies by distribution and installed version. Ubuntu systems may use php8.2-fpm, while another supported PHP version may be active.
Check compute, queues, and storage
On Linux, inspect CPU pressure, memory, and disk wait:
uptime
free -h
vmstat 1 5
iostat -xz 1 5
High CPU run queue values, memory pressure, swap activity, or elevated disk utilization can explain a slow TTFB even with a clean MTR. Check active processes:
ps -eo pid,ppid,comm,%cpu,%mem,state --sort=-%cpu | head
For PostgreSQL, inspect active queries:
sudo -u postgres psql -c "SELECT pid, now() - query_start AS duration, wait_event_type, state, query FROM pg_stat_activity WHERE state <> 'idle' ORDER BY query_start;"
For MySQL or MariaDB:
mysql -e "SHOW FULL PROCESSLIST;"
What this looks like in production: On a busy VPS node, application latency often rises during backups, scans, or database maintenance. The network graph stays clean because the packets arrive, but the server doesn't produce the first byte promptly. Bare metal removes some shared-resource uncertainty, but it doesn't excuse an unindexed query or a saturated process pool.
Proven Ways to Lower Latency for Good
Fix the phase that measured slowest. Changing storage won't repair a bad route, and adding bandwidth won't make an application worker finish faster.
1. Improve placement and delivery
Place the origin near the users and dependent services that generate the most requests. Cache static assets at an edge, reduce unnecessary cross-region calls, and keep application components close enough that critical requests don't cross avoidable network boundaries.
For a web server using Nginx, confirm keepalive and HTTP/2 behavior before changing configuration:
nginx -T | grep -E 'listen .*http2|keepalive_timeout|keepalive_requests'
A conservative configuration might look like:
http {
    keepalive_timeout 65s;
    keepalive_requests 1000;

    server {
        listen 443 ssl http2;
        server_name example.com;
    }
}
Test and reload safely:
sudo nginx -t
sudo systemctl reload nginx
curl -sS -I --http2
If the test fails, restore the previous file and reload:
sudo cp /etc/nginx/nginx.conf.bak /etc/nginx/nginx.conf
sudo nginx -t && sudo systemctl reload nginx
2. Reduce origin work
Measure TTFB before and after each change. Enable application caching where content permits, reuse connections, and remove avoidable upstream calls from the critical request path. Don't increase worker counts blindly. Too many workers can replace a queue with CPU contention.
A simple verification loop is:
for i in $(seq 1 10); do
  curl -sS -o /dev/null -w 'ttfb=%{time_starttransfer} total=%{time_total}n'
done
Common failure mode: a cache hides a slow origin for one URL while uncached pages remain poor. Test representative authenticated, uncached, and dynamic requests separately.
3. Fix storage and database contention
Check I/O while the slow request runs:
iostat -xz 1 10
Then inspect slow queries using the database's native tooling. Add an index only after confirming the query pattern and execution plan. A database index can improve reads but adds write and storage overhead, so document the change and keep a rollback statement ready.
For workloads with sustained I/O contention, dense virtualization, large databases, or AI inference, dedicated resources may be more appropriate than continued VPS tuning. ARPHost provides bare metal servers and colocation in Tampa for workloads that need direct hardware access, predictable storage, or on-site remote hands.
4. Apply one change, then verify
Record the baseline, make one change, run the same tests, and watch p75 and p95 over a representative operating period. If results worsen, revert the single change rather than stacking another adjustment on top. ARPHost's latency reduction guidance is useful as a companion checklist, but production validation still belongs to your environment.
Choosing Your Target and Preventing Future Lag
Choose the metric that represents the user's complaint. For a website, track p75 TTFB and Core Web Vitals. For a real-time service, track latency distribution, jitter, and packet loss. For AI, track TTFT and the slower tail of complete responses. Averages can hide the users who encounter the actual problem.
Use this maintenance checklist:
- Measure from real locations: Test the user path, server path, and an independent location.
- Watch percentiles: Review p75 for web experience and p95 or p99 for tail behavior.
- Correlate layers: Compare MTR, curl timings, application logs, database waits, CPU, memory, and storage.
- Protect headroom: Schedule backups and maintenance so they don't compete with interactive traffic.
- Document rollback: Keep the previous configuration and the verification command beside every change.
Escalate when loss reaches the destination, a route changes unexpectedly, TTFB remains high after application review, or storage and compute are consistently constrained. In Tampa, local remote hands can also matter when a physical link, server component, or power event requires inspection rather than another software change.
ARPHost, LLC operates VPS, bare metal, colocation, Proxmox private clouds, secure web hosting, and managed IT infrastructure from Tampa, Florida. If your measurements show persistent path, storage, or origin latency, visit ARPHost, LLC to discuss a deployment built around the metrics your workload needs.
Leave a Reply
You must be logged in to post a comment.