A new host goes into service. The invoice says NVMe, the drive label says NVMe, and every dashboard is green because every dashboard only checks that the device exists. Three weeks later the backup window overlaps peak traffic, VM guests start reporting I/O timeouts, and the drive turns out to be negotiating two PCIe lanes instead of four, or it's a client-grade part whose write endurance is being eaten by logs and nightly images.
The fix isn't a more expensive drive. It's a better requirement. An NVMe SSD requirement worth writing down covers five things: usable bytes per namespace, the PCIe width and generation the slot provides, an endurance class in both DWPD and TBW, latency at the queue depth your workload really generates, and whether power-loss protection is present. Everything else on the data sheet is marketing.
What follows is the checklist I'd run on any host before a drive enters production, with the commands that prove each item and the failures that only appear under load.
Table of Contents
- NVMe SSD Requirements by Workload at a Glance
- Confirming Detection, Namespaces and OS Support
- PCIe Lanes and Interface Speed That Limit Real Throughput
- Queue Depth and Latency Targets Worth Requiring
- Endurance Ratings, DWPD and Overprovisioning Needs
- Power, Cooling, RAID and TRIM for Hosted Servers
- Checking NVMe Health Before You Sign Off a Drive
NVMe SSD Requirements by Workload at a Glance
Five workload shapes cover nearly every requirement in hosting, and once a server is placed in one of them the spec writes itself. The table is the minimum I'd accept per row: interface and form factor, endurance target, power-loss protection, and the capacity figure that goes on the purchase order.
| Workload | Interface and form factor | Endurance target | Power-loss protection | Capacity to specify |
|---|---|---|---|---|
| Shared web hosting and VPS nodes | PCIe 3.0 or 4.0 x4, M.2 M-key or U.2 | 1 to 3 DWPD depending on write mix | Recommended | Usable bytes per namespace plus spare space for garbage collection |
| Proxmox virtualization nodes | PCIe 4.0 x4, M.2 or U.2 | 3 DWPD mixed use | Required for synchronous writes | Separate boot volume and VM storage volume |
| MySQL and PostgreSQL servers | PCIe 4.0 x4 or PCIe 5.0 x4 | 3 to 10 DWPD | Required | Data files plus WAL or binlog space |
| Backup staging and replication targets | PCIe 3.0 x4 or better | 1 DWPD for restore reads, 3 DWPD for ingest | Recommended | Retention window multiplied by daily change rate |
| Boot-only OS drive | PCIe 3.0 x4 M.2 M-key, firmware with NVMe boot support | 1 DWPD | Optional | Confirm the installer sees the intended namespace |
The interface column sets the ceiling before the drive talks to the OS. A Gen4 drive in a Gen3 x4 slot works perfectly at half the bandwidth, which is fine for a boot volume and wrong for a database host. The endurance column is the one buyers skip, and the power-loss column is the one that decides whether a committed transaction survives a power event.
Why the label is not a specification
"NVMe" names a command protocol. It doesn't pin down PCIe generation, lane width, namespace layout, boot firmware support, or endurance class, as the Linux kernel NVMe feature and quirk policy points out. That same documentation shows how to separate physical controller capacity from usable namespace capacity: nvme list reports the namespaces currently exposed to the OS, nvme id-ctrl /dev/nvme0 reports controller properties, and nvme id-ns /dev/nvme0n1 reports namespace details.
That gap produces a boring, common failure. A server passes procurement because it contains an NVMe SSD, then the installer sees the wrong namespace size or can't boot from the installed firmware configuration.
The three figures on the purchase order
Write these down as numbers, not adjectives: usable bytes per namespace, endurance in DWPD and TBW, and the required namespace count. Add the PCIe link you expect and whether the drive must boot.
If you're weighing tiers for smaller workloads, NVMe versus SSD storage on a VPS covers which one changes application behavior. Densified virtualization clusters and large databases usually justify dedicated hardware where the board, not just the drive, is specified for the job.
Confirming Detection, Namespaces and OS Support
A drive that appears in the BIOS is not a drive that's ready to boot. The first check on any new or replacement NVMe device is whether the host sees the controller, the namespace, and a boot path, in that order. A module can be seated correctly, keyed correctly, and still be invisible to the installer because the socket is wired for SATA only or the firmware has no NVMe boot entry.
Controller versus namespace
Linux names the two separately. /dev/nvme0 is the controller; /dev/nvme0n1 is a namespace on it. The kernel NVMe subsystem documentation is explicit that a controller can exist without the expected namespace being attached or visible, which is exactly the state that sends a technician into an OS reinstall that was never the problem.
Run these in order and record what each returns:
uname -r
lspci -nn | grep -i nvme
lsblk -e7 -o NAME,MODEL,SERIAL,SIZE,TYPE,FSTYPE,MOUNTPOINTS
sudo nvme list
A healthy local drive looks like this. PCIe discovery, one namespace, model and serial matching the slot you installed it in:
$ lspci -nn | grep -i nvme
01:00.0 Non-Volatile memory controller [0108]: Samsung Electronics Co Ltd NVMe SSD Controller [144d:a80a]

$ sudo nvme list
Node             SN                  Model                    Namespace  Usage                    Format        FW Rev
/dev/nvme0n1     S6B0NL0T512345A     SAMSUNG MZQL23T8HCLS-00A07   1       3.84 TB / 3.84 TB   512 B + 0 B   GDC5
If the namespace layout still doesn't make sense after those four commands, this walkthrough of how the subsystem is organized on Linux is worth the time before you touch the installer.
The failing case looks different. The controller is on the bus, but no block device appears:
$ dmesg -T | grep -iE 'nvme|pcie|aer'
[Mon Mar 10 09:14:02 2025] pcieport 0000:00:01.0: AER: Corrected error received: 0000:01:00.0
[Mon Mar 10 09:14:02 2025] nvme nvme0: Removing after probe failure status: -19

$ ls -l /dev/nvme*
crw------- 1 root root 240, 0 Mar 10 09:14 /dev/nvme0
Controller present, namespace absent, is a firmware or configuration problem. Compare dmesg -T | grep -iE 'nvme|pcie|aer' against ls /dev/nvme* and you can tell a controller fault from a namespace attachment problem in under a minute.
What to check before reinstalling the OS
Work through these in order: firmware revision, slot bifurcation, namespace attachment, then kernel compatibility. Confirm the firmware boot mode is UEFI with an NVMe boot entry present. None of these are fixed by wiping the disk.
Record three values in the host inventory, because behavior differs between releases and the record is the only way to reproduce a fault later: the kernel release from uname -r, the tooling version from nvme version, and the firmware revision from sudo smartctl -i /dev/nvme0.
On a multi-tenant Proxmox host this distinction matters more than on a laptop. A controller-level fault surfaces in several guests at once, and the guests only report I/O timeouts. The host log is where the evidence lives, not the guest console.
PCIe Lanes and Interface Speed That Limit Real Throughput
An NVMe drive doesn't get a private bus to the CPU. It gets a fixed number of PCIe lanes at a fixed generation, and that link is the ceiling on everything else. A Gen4 drive in a Gen3 slot negotiates down and works perfectly at half the bandwidth. An x4 drive in a socket wired for two lanes runs at x2. Neither condition raises a warning, an error, or a degraded flag.
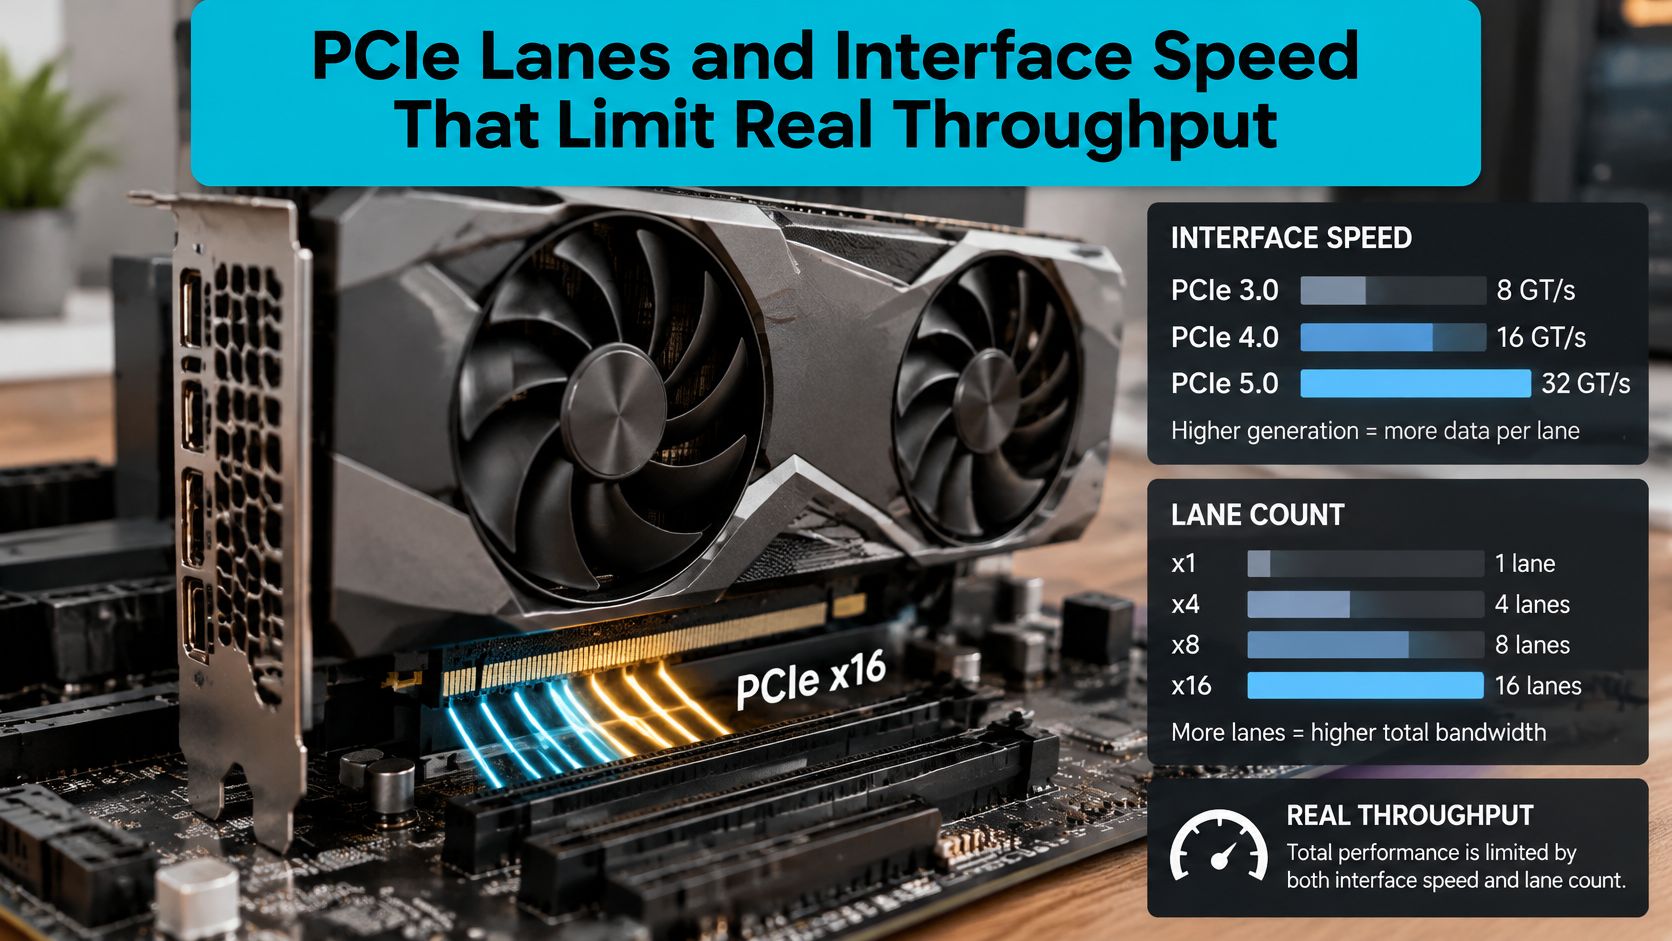
| PCIe generation | Lanes per drive | Approximate usable bandwidth per direction | Typical placement |
|---|---|---|---|
| PCIe 3.0 | x4 | about 3.9 GB/s | Older servers, boot drives, backup staging |
| PCIe 4.0 | x4 | about 7.9 GB/s | Most current VPS and virtualization nodes |
| PCIe 5.0 | x4 | about 15.8 GB/s | High-throughput database and data pipeline hosts |
| PCIe 4.0 | x2 | about 3.9 GB/s | Lane-limited slots and shared chipset paths |
The form factor trap
An M.2 slot's key only controls whether the module fits. An M-keyed socket may be routed for PCIe only, SATA only, or both, and a SATA module will seat in a PCIe-only socket and never be detected. B+M keying gives the widest mechanical fit but caps the link at PCIe x2 or SATA. U.2 and E3.S bays are worse in one respect: they need a backplane that routes PCIe to that bay, and a bay that carries only SATA signalling won't show you an NVMe drive no matter what you plug in.
Lane sharing is the quiet culprit on populated boards. M.2 slots attached through the chipset share an uplink with SATA ports, NICs and HBAs, so populating a second M.2 slot can drop the first one to x2 or disable a neighbouring port entirely. The board manual states which slots share; read it before the order, not after.
Reading LnkCap against LnkSta
Take the device address from lspci and ask the kernel what the link negotiated:
sudo lspci -vv -s 01:00.0 | grep -E 'LnkCap|LnkSta'
        LnkCap:	Port #0, Speed 16GT/s, Width x4, ASPM L1, Exit Latency L1 <8us
        LnkSta:	Speed 8GT/s, Width x2 (downgraded)
LnkCap is what the slot and drive can do together. LnkSta is what they settled on. A mismatch here means a riser, a shared slot, a bifurcation setting, or a seated-but-not-quite card. For multi-drive riser cards, PCIe bifurcation must be set in BIOS (x16 into x4/x4/x4/x4, for example), and the board has to support that split.
Commissioning rule: check
LnkStaon every host you build. A link that trained at x2 reports full capacity in every tool that lists drive size, so capacity dashboards will never catch it.
Confirm lane width and generation per slot before ordering drives. It's a two-minute check that saves a support ticket six weeks later.
Queue Depth and Latency Targets Worth Requiring
Most buyers compare the peak IOPS number on the spec sheet and stop there. That figure describes a drive with dozens of outstanding requests and an empty flash array, and it tells you very little about a WordPress node serving single synchronous writes.
Why peak IOPS numbers mislead
Queue depth is the count of I/O requests the host has outstanding at once. More parallelism keeps more flash dies busy, so throughput climbs, until it saturates. Latency moves the other way the whole time, because each request waits behind everything queued ahead of it. Intel's enterprise NVMe benchmarking paper recommends testing mixed read/write workloads across multiple queue depths instead of relying on all-read or all-write specifications, and notes that throughput changes only slightly once queue depth exceeds approximately 64. A workload that can't generate parallel I/O will never touch the headline number.
That cuts both ways. A VPS or a small WordPress site lives on low-depth latency and consistent tail latency, so a drive with an excellent queue-depth-1 profile beats one with a spectacular peak. VM consolidation, backup jobs and databases do exploit higher depths, but only with CPU, PCIe bandwidth and controller headroom to match, otherwise the queue just fills with contention.
Running the sweep
Test against a scratch file on a volume you can destroy, never on production data:
fio --name=qd8 --filename=/mnt/scratch/fio.dat --size=4G --rw=randrw
  --rwmixread=70 --bs=4k --iodepth=8 --numjobs=1 --direct=1
  --ioengine=libaio --runtime=120 --time_based --group_reporting
  --percentile_list=95:99
Run the same job at --iodepth=1, 8, 32 and 64. Read two things: the IOPS line for how much work got done, and the completion latency block for what a slow request cost.
  clat percentiles (usec):
   |  1.00th=[  112], 5.00th=[  130], 10.00th=[  138], 20.00th=[  148],
   | 30.00th=[  157], 40.00th=[  166], 50.00th=[  176], 60.00th=[  187],
   | 70.00th=[  200], 80.00th=[  219], 90.00th=[  249], 95.00th=[  281],
   | 99.00th=[  486], 99.50th=[  652], 99.90th=[ 1254], 99.95th=[ 2146],
   | 99.99th=[ 5014]
The 99.00th value is what one request in a hundred sees. The 99.99th is what your monitoring reports as a slow query at 3 a.m.
Repeat the same sweep while a backup or replication job is running. The numbers that matter appear then, because a drive that folds under concurrent load passes every idle benchmark ever written.
A useful acceptance criterion isn't maximum IOPS. It's whether latency stays inside the application's service-level target at the aggregate queue depth you expect.
File the sweep results with the purchase record. Six months later, when a node feels slow, you'll want to know what it measured on day one.
Endurance Ratings, DWPD and Overprovisioning Needs
A drive can pass an initial performance check while its write budget steadily drains under VM churn, logs and backup staging. Size endurance for the workload's daily host writes, not just the drive's capacity.
DWPD measures how many times the drive's usable capacity can be written each day over its rated warranty period. For example, a 3.84 TB drive rated at 3 DWPD is designed for roughly 11.52 TB of host writes per day. The SNIA NVMe SSD classification white paper places read-intensive drives at about 1 DWPD, mixed-use at 3 DWPD, and write-intensive at 5 to 10 DWPD.
| Endurance class | Rating | Host writes per day on 3.84 TB | Typical workload |
|---|---|---|---|
| Read-intensive | About 1 DWPD | 3.84 TB | Static content and read caches |
| Mixed-use | 3 DWPD | 11.52 TB | VPS fleets, databases and logging |
| Write-intensive | 5 to 10 DWPD | 19.2 to 38.4 TB | Journals, high-churn queues and hot caches |
Write amplification and overprovisioning
The host's write count understates the work the flash performs. Garbage collection and wear leveling add internal writes, and background maintenance can cause occasional latency spikes. On a shared host, sustained random writes from several tenants can keep those operations busy and expose the limits of a drive that looked adequate in a short test.
Leave a meaningful share of raw capacity unpartitioned on write-heavy volumes. The controller can use those free blocks for relocation and garbage collection. For databases, mail queues and other workloads with fsync in the hot path, require power-loss protection so completed writes remain durable.
Watching the write budget
sudo nvme smart-log /dev/nvme0 | grep -E 'data_units_written|percentage_used'
data_units_written                    : 1,234,567
percentage_used                       : 3%
Each data unit represents 1000 units of 512 bytes. The example count is roughly 632 GB of host writes, while percentage_used reports 3% of the drive's rated life consumed. Track both readings over time; a steep rise in a month points to a workload that needs attention.
Placement decision: Logging, VM images and backup staging can consume endurance quickly. Put them on separate volumes from latency-sensitive production workloads.
Choose an endurance class from the volume's measured write profile, then compare the drive's write budget with the workload it will carry.
Power, Cooling, RAID and TRIM for Hosted Servers
A drive can pass detection and still misbehave under sustained load. Check its power policy, the PCIe path to the device, the RAID layout, and whether discard reaches the storage. On a shared host, a configuration that looks correct on paper can still limit throughput or leave a boot volume unprotected.
Checking the power state
NVMe drives can throttle as temperatures rise. Dense chassis and sustained writes make airflow and power policy worth checking before deployment. An M.2 heatsink may help when chassis airflow is insufficient. Inspect the current power state:
sudo nvme get-feature /dev/nvme0 -f 2 -H
get-feature:0x02 (Power Management), Current value:0x00
    Current Power State: 0 (0x0)
Deeper power states reduce idle draw but can add wake latency, which may affect tail latency. For latency-sensitive workloads, test the drive's configured power policy under representative load rather than assuming the default is suitable. Also confirm the server's power budget accounts for add-in cards and populated multi-drive risers.
RAID and TRIM
For a mirrored boot volume, verify that software RAID assembled both devices:
cat /proc/mdstat
Personalities : [raid1]
md0 : active raid1 nvme1n1p2[1] nvme0n1p2[0]
      194805760 blocks super 1.2 [2/2] [UU]
Many hardware RAID controllers do not pass NVMe through. Confirm pass-through or JBOD support before ordering a controller. For TRIM, check that discard is exposed on the device path, run it manually, and confirm the scheduled timer:
lsblk --discard /dev/nvme0n1
sudo fstrim -v /
systemctl status fstrim.timer
NAME        DISC-ALN DISC-GRAN DISC-MAX DISC-ZERO
nvme0n1            0      512B       2T         0

/: 812.4 GiB (872255750144 bytes) trimmed

     Loaded: loaded (/lib/systemd/system/fstrim.timer; enabled; preset: enabled)
     Active: active (waiting) since Mon 2025-03-10 00:12:44 UTC; 1 day 9h ago
    Trigger: Mon 2025-03-17 00:12:44 UTC; 5 days left
If DISC-GRAN is missing, discard is not available through that path. Verify discard support across the full storage stack, especially for thin-provisioned volumes.
ARPHost's Tampa datacenter has redundant power systems with UPS and diesel generators, and N+1 precision cooling. Redundant uplinks or power feeds are not included with every service by default, so discuss those requirements with the team when selecting a configuration. For mirrored boot volumes, server RAID configurations describes RAID layouts and verification. Record chassis airflow and the power budget alongside the drive specification; both help pinpoint throttling when a host is under load.
Checking NVMe Health Before You Sign Off a Drive
A drive can stay online while its health declines, and a clean command exit does not prove it is fit for service. Before sign-off, confirm its serial number against the physical bay and check the NVMe health log:
sudo nvme list
sudo nvme smart-log /dev/nvme0
sudo smartctl -x /dev/nvme0
Smart Log for NVME device:nvme0 namespace-id:ffffffff
critical_warning                        : 0
temperature                             : 35 C
available_spare                         : 100%
available_spare_threshold               : 10%
percentage_used                         : 0%
media_errors                            : 0
Use the health log's reported threshold, not a guessed universal cutoff. A nonzero critical_warning, available spare at or below its threshold, or a rising percentage_used warrants investigation. Host command counts and controller busy time can also help distinguish sustained application load from a drive-health problem.
On a virtualization host, collect the log regularly and correlate changes with iostat -x 5 and kernel messages. This can expose a drive that remains online while temperature, media errors, or spare capacity worsen. Save diagnostic output before replacement; transient evidence may be lost after a reboot.
Match the serial from nvme list to the physical drive before service, especially when identical drives occupy multiple bays. A serial mismatch can turn a correct diagnosis into removal of the wrong device.
Escalation: Available spare at or below the device-reported threshold calls for replacement, not routine monitoring.
Dedicated and VPS customers have secure remote access tools, real-time monitoring and insights, remote reboot capability through the client portal, and access to the Knowledgebase. Standard deployments have faulty hardware repaired or replaced within 5 hours. Teams can also use managed infrastructure services for security updates, vulnerability scanning, and hardening. A consistent infrastructure monitoring routine helps put drive-health checks alongside host-level signals.
ARPHost, LLC uses NVMe SSD storage across its infrastructure, including Tampa-hosted VPS and bare metal services. For a hosted drive, record the device identity and health readings so that monitoring and service teams can act on the same evidence. See ARPHost, LLC for platform details.
Leave a Reply
You must be logged in to post a comment.